Wan 2.5 免费在线 AI 视频生成器,已升级为 Wan 3.0
Yovid 并未提供 Wan 2.5,提供的是 Alibaba 的继任模型 Wan 3.0。它保留了让 2.5 出彩的人声、音乐和音效,并把视频从 10 秒延长到最长 30 秒。可以从提示词、首帧,或最多 10 张图片和 5 段视频开始。 现在就在 Yovid 上用 Wan 3.0 开始创作。
Wan 3.0 在 Yovid 上能拍出什么画面
Wan 3.0 为什么在 Yovid 上取代 Wan 2.5
- Yovid 提供的是 Wan 3.0,不是 Wan 2.5:Wan 2.5 是 2025 年的预览版;此后已推出三个更新的版本,Yovid 提供的是最新的。
- Wan 3.0 长达 30 秒,是 Wan 2.5 的三倍:Wan 2.5 最长 10 秒;Yovid 上的 Wan 3.0 可设 2 到 30 秒。
- Wan 2.5 把声音带进了同一次生成:人声、音效和音乐与画面一起生成,Wan 3.0 默认同样开启。
- 用你写的语言,口型同步的对白:Wan 3.0 用你给的语言配出每一句台词,并对上正确的嘴。
- 最多 10 张图片和 5 段视频作为参考:Wan 2.5 只能从文字或一张图片出发;Wan 3.0 接受一整组参考素材。
- 装得下完整分镜表:10,000 个字符的提示词:带时间码的镜头、运镜、配乐提示和每一句对白,一条提示词就放得下。
- Yovid 上的 Wan 3.0 设置与积分:2–30 秒、3 档分辨率、6 种画面选项,声音包含在内,每秒约 1.2 积分起。
Yovid 提供的是 Wan 3.0,不是 Wan 2.5
Alibaba 于 2025 年 9 月在 Alibaba Cloud Model Studio 上以预览形式发布 Wan 2.5,是托管模型,而不像 Wan 2.1 和 2.2 那样提供可下载的权重。它的亮点是声音:对白、音效和音乐与画面一起生成,视频为 5 或 10 秒,最高 1080p。
Wan 2.6、Wan 2.7 和 Wan 3.0 在一年内陆续推出。Yovid 只提供 Wan 3.0,所以本页的输入框默认就是它,你在这里生成的每条视频也都来自它。下表列出了每一步新增了什么。
| Wan 2.5 · 2025 年 9 月 | 5 或 10 秒,原生声音从文字或首帧生成 480p、720p 或 1080p;提示词最多 1,500 个字符。 |
|---|---|
| Wan 2.6 · 2025 年 12 月 | 最长 15 秒,多镜头新增参考生成视频,让人物的外貌和声音保持一致。 |
| Wan 2.7 · 2026 年 4 月 | 最长 15 秒,并支持视频编辑最多 5 个图片与视频混合的参考;提示词最多 5,000 个字符。 |
| Wan 3.0 · 2026 年 8 月 | 最长 30 秒,也是 Yovid 上的版本人脸更逼真多样,对参考素材的还原也更到位。 |
Wan 3.0 长达 30 秒,是 Wan 2.5 的三倍
10 秒只够一个镜头,30 秒却能装下有铺垫、有转折、有收尾的完整场景。左边是 10 秒的 Wan 2.5 演示:一位记者、一句台词、一个跟拍镜头。右边是 30 秒的 Wan 3.0 演示,用四张参考图,配上日语旁白,通过两条时间线讲述一场重逢。
在 Yovid 上,时长是一个滑块,2 到 30 之间的任意整数秒都行,价格也随你选的秒数变化。先用短版本验证想法,提示词跑通之后,再按完整时长生成。
| Wan 2.5 · 10 秒 | Wan 3.0 · 30 秒 |
|---|---|
Wan 2.5 把声音带进了同一次生成
声音与画面一起生成,是 Wan 2.5 的招牌功能:一句台词对上说话人的嘴,一个脚步落在脚掌着地的那一帧。这条 10 秒的 Wan 2.5 Preview 演示里,一位老北京用地道的京腔跟邻居打招呼,笼子里的画眉鸟也准时啼叫。
Wan 3.0 保留了这一点,还给了它更大的空间。在 Yovid 上,声音默认开启,不额外收积分,因为一条视频无论开不开声音,价格都一样。把每句台词放进引号,写明是谁、用什么语言说;打算自己配乐时,再关掉声音。
提示词(节选): Early autumn morning in a Beijing hutong, warm side light on grey flagstones, an old pagoda tree swaying in the breeze. A man in his sixties in a navy cotton jacket and cloth shoes carries a rosewood birdcage; the thrush inside chirps twice. He meets a neighbor, smiles, nods and says in a broad Beijing accent: "哟,吃了么您呐?没事儿遛遛弯儿,舒坦!" (Eaten yet? Just out for a stroll. Feels great!) The cage sways as the bird flutters; pots of jasmine stir by the grey brick wall.
用你写的语言,口型同步的对白
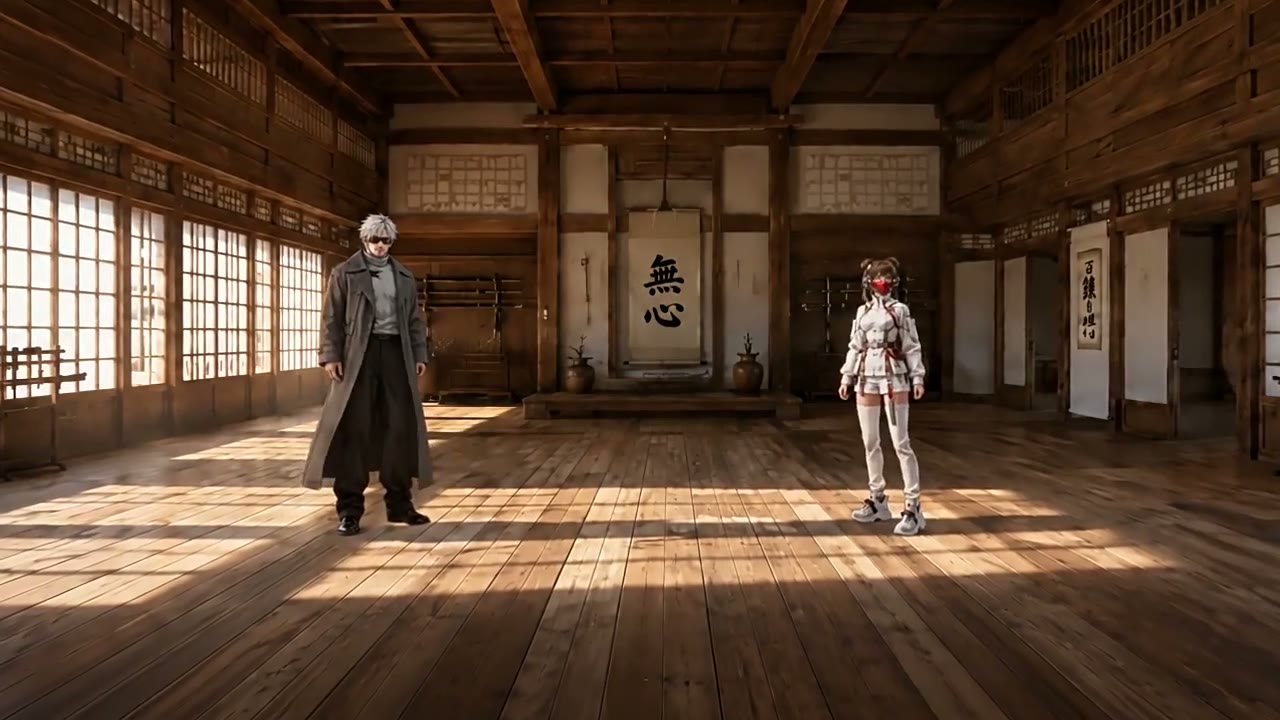
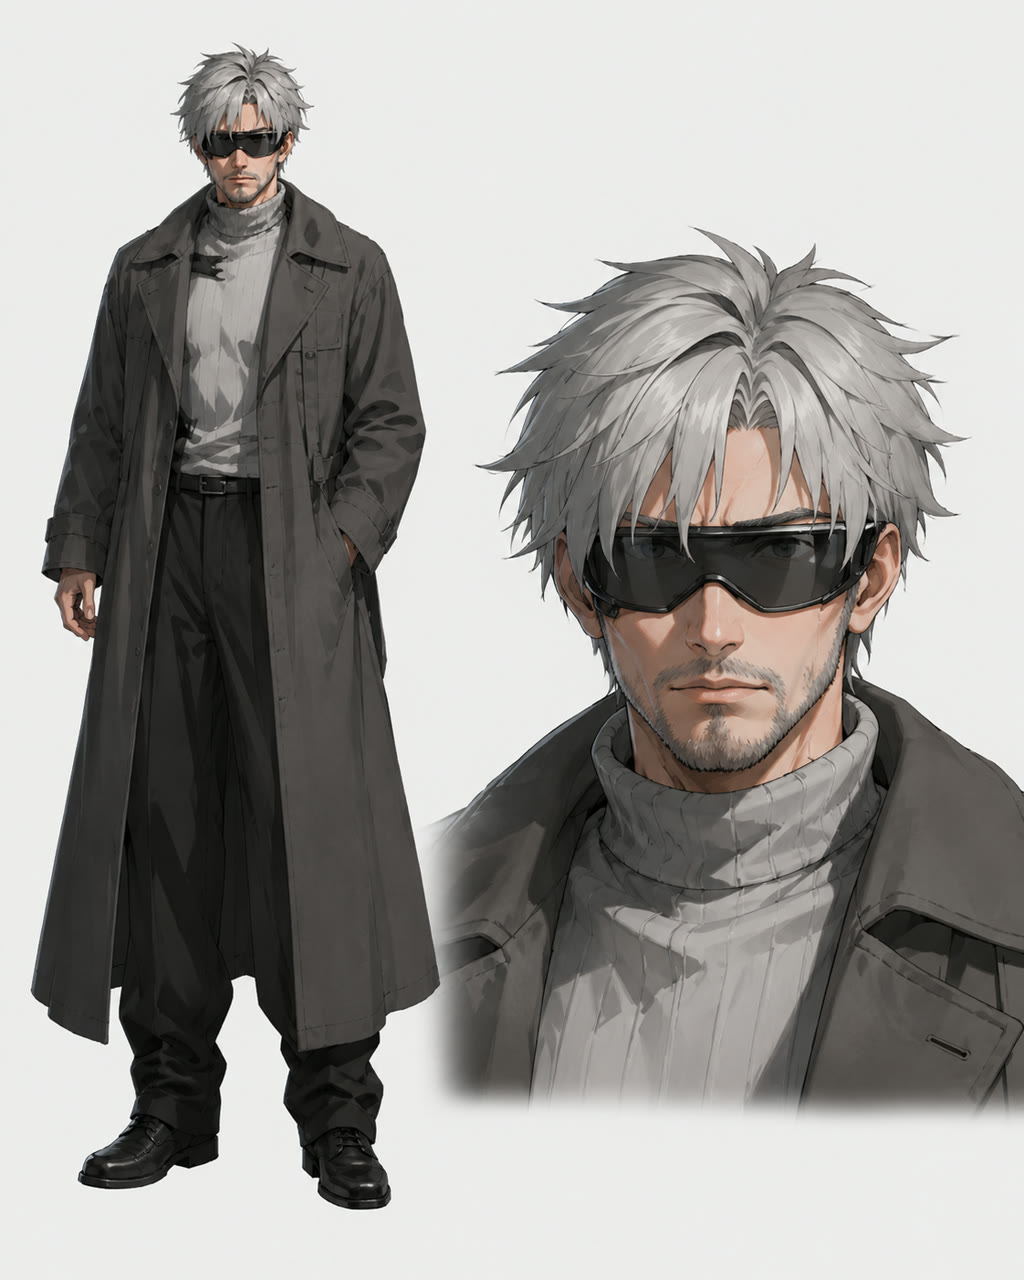
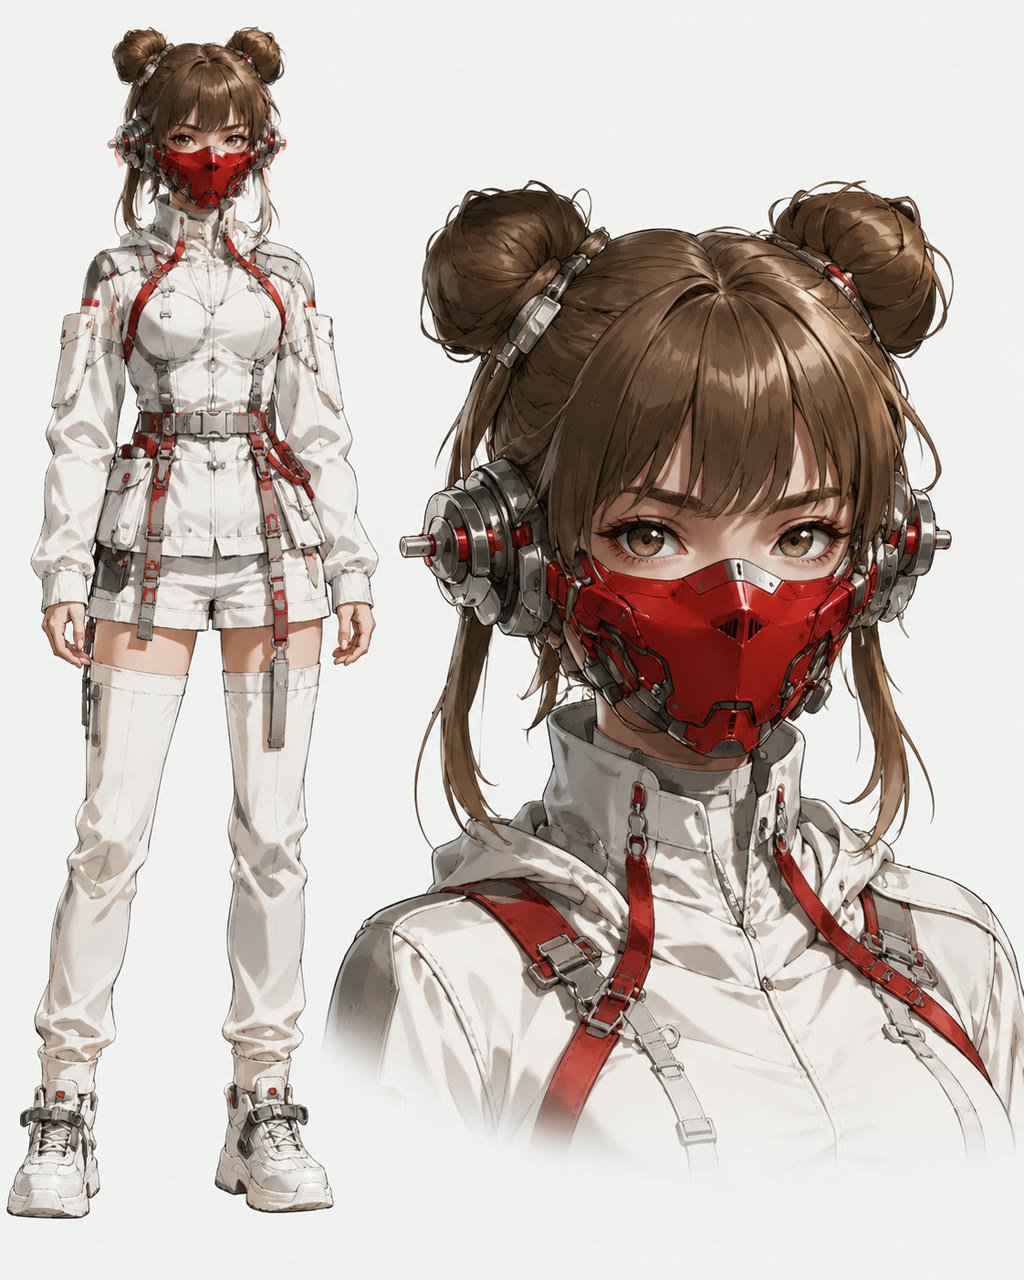
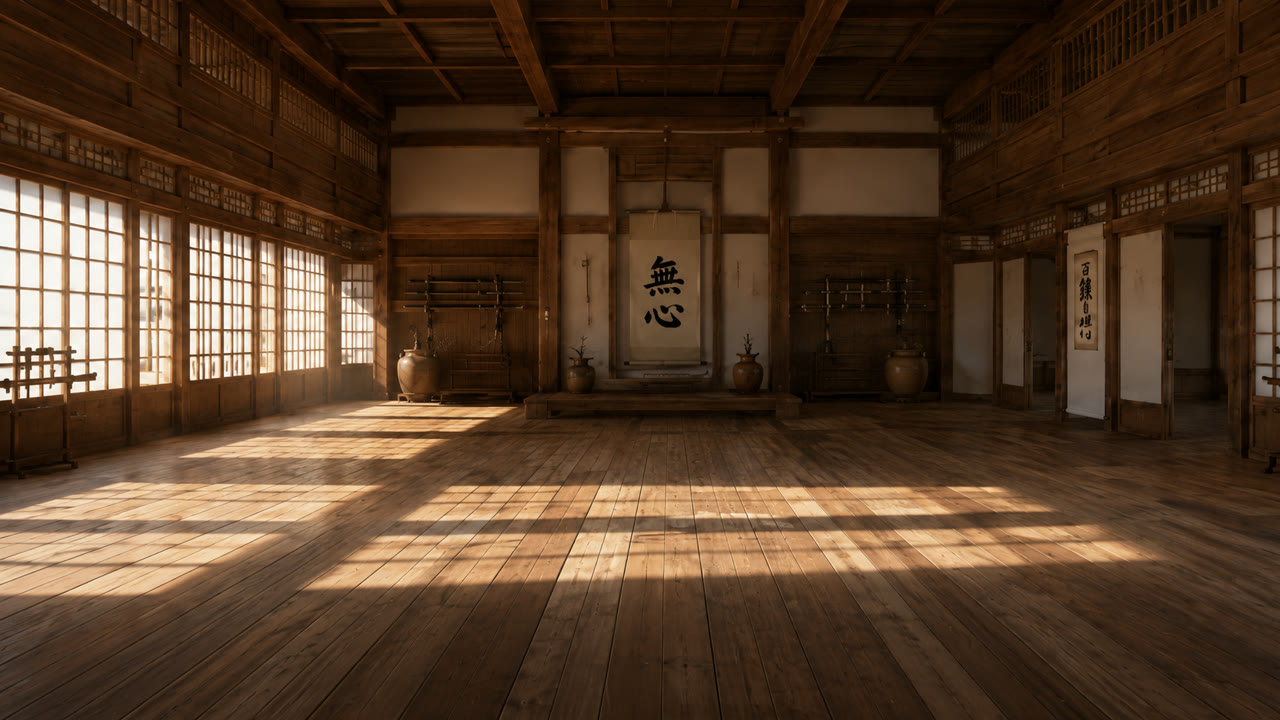
写下台词,指明说话人和语言,Wan 3.0 就会连同对应的口型一起说出来。在这条 24 秒的演示里,三张参考图固定了两个游戏角色和一座道场:她问这是什么地方,他告诉她这是她的第一道试炼,冰冷的系统语音宣布测试开始,全程日语,每句都对上了正确的嘴。
Alibaba 的其他 Wan 3.0 演示里,还有英语、普通话、韩语、葡萄牙语、泰语、西班牙语和阿拉伯语的台词。再加一点语气说明,比如低沉平静或急促紧张,让配音贴合场景。
 Wan 3.0
最多 10 张图片和 5 段视频作为参考
Wan 2.5 从文字提示词,或作为首帧的单张图片开始。Yovid 上的 Wan 3.0 多了参考模式:最多 10 张图片和 5 段各 1 到 15 秒的视频,负责锁定人物、生物、产品和场景,提示词则负责指挥它们。
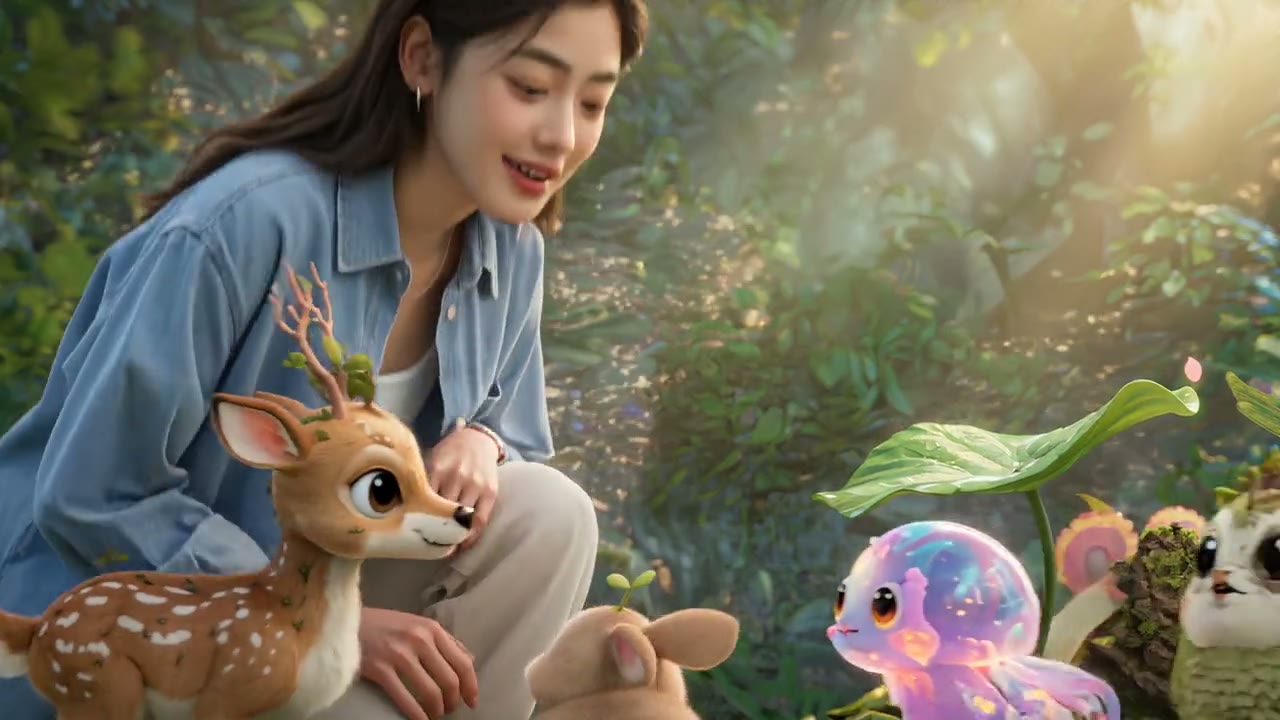
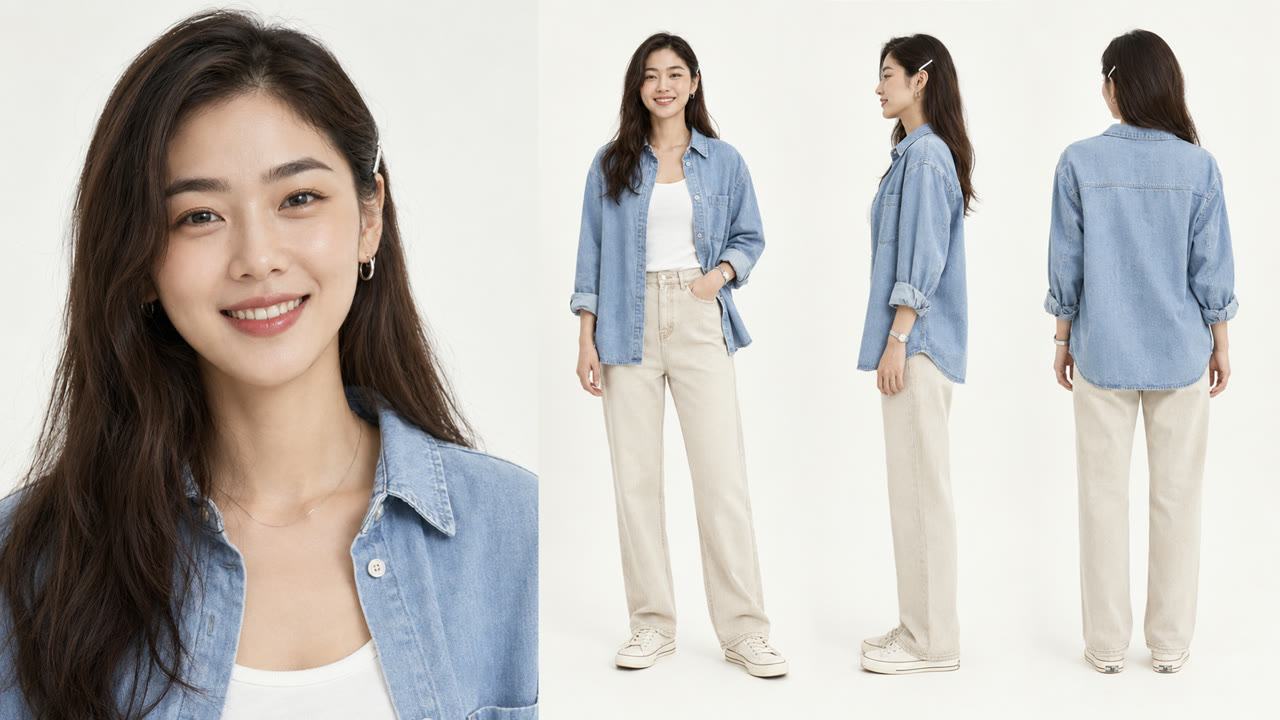
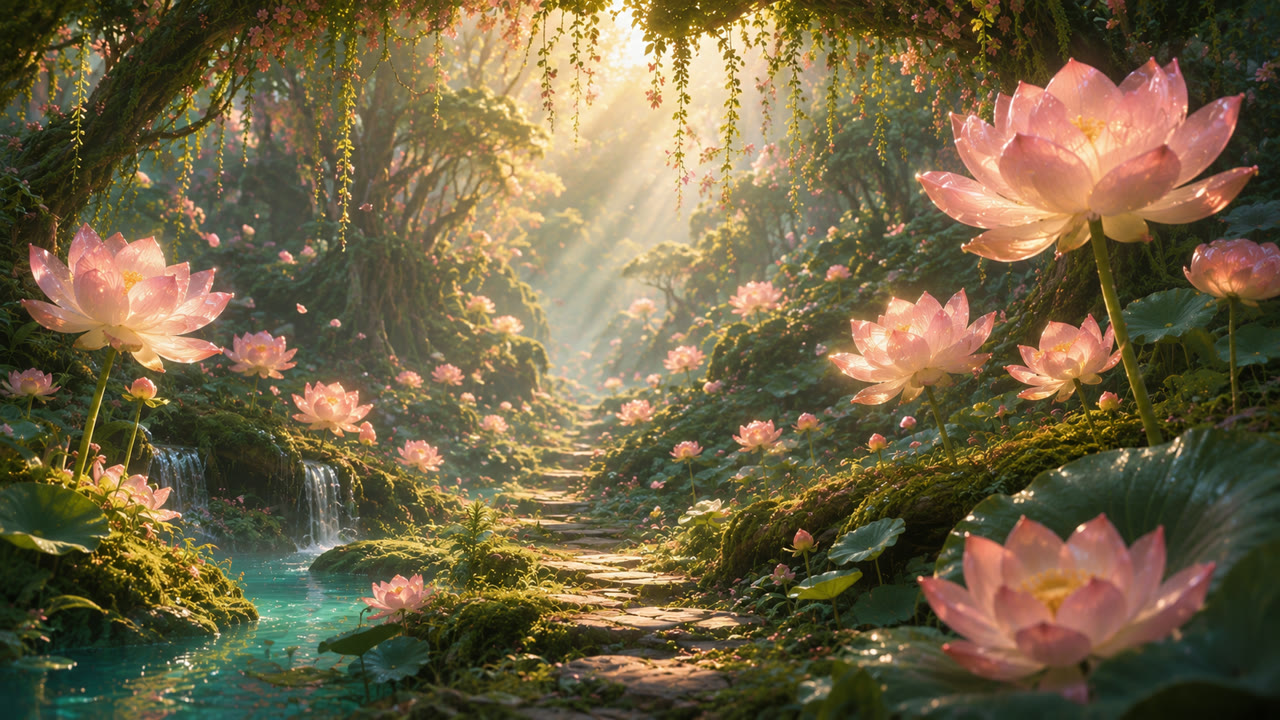
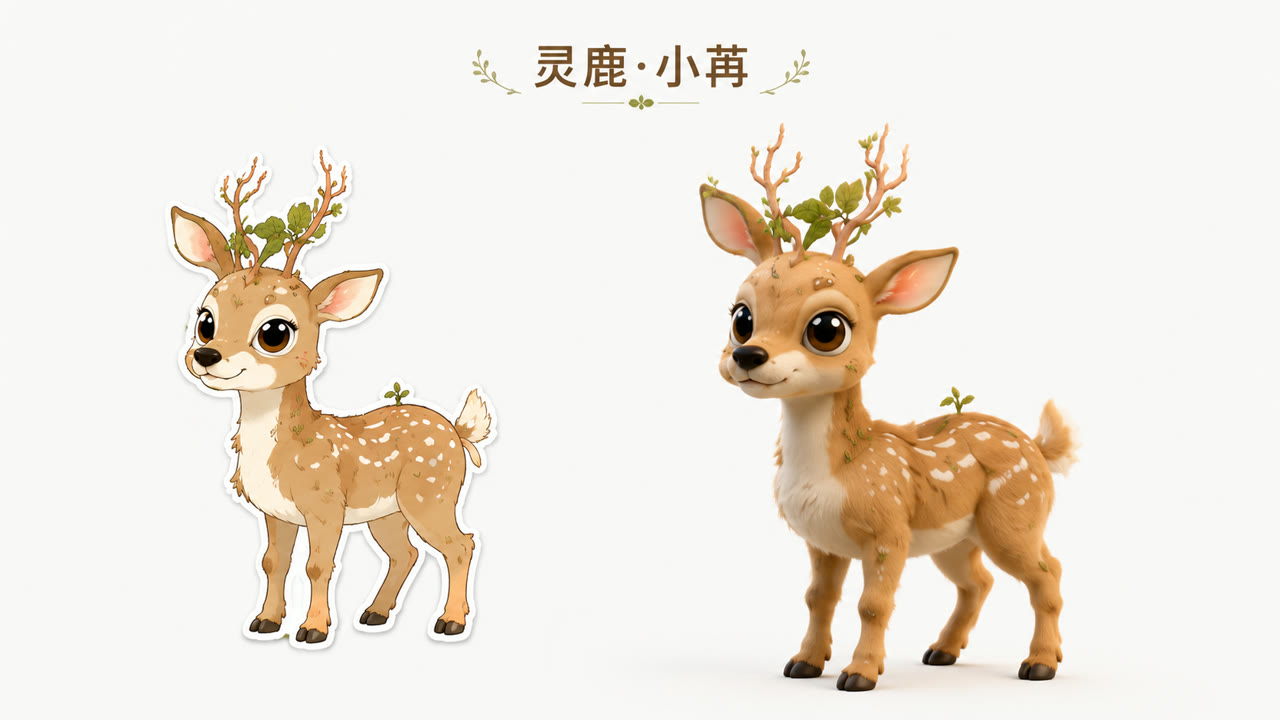
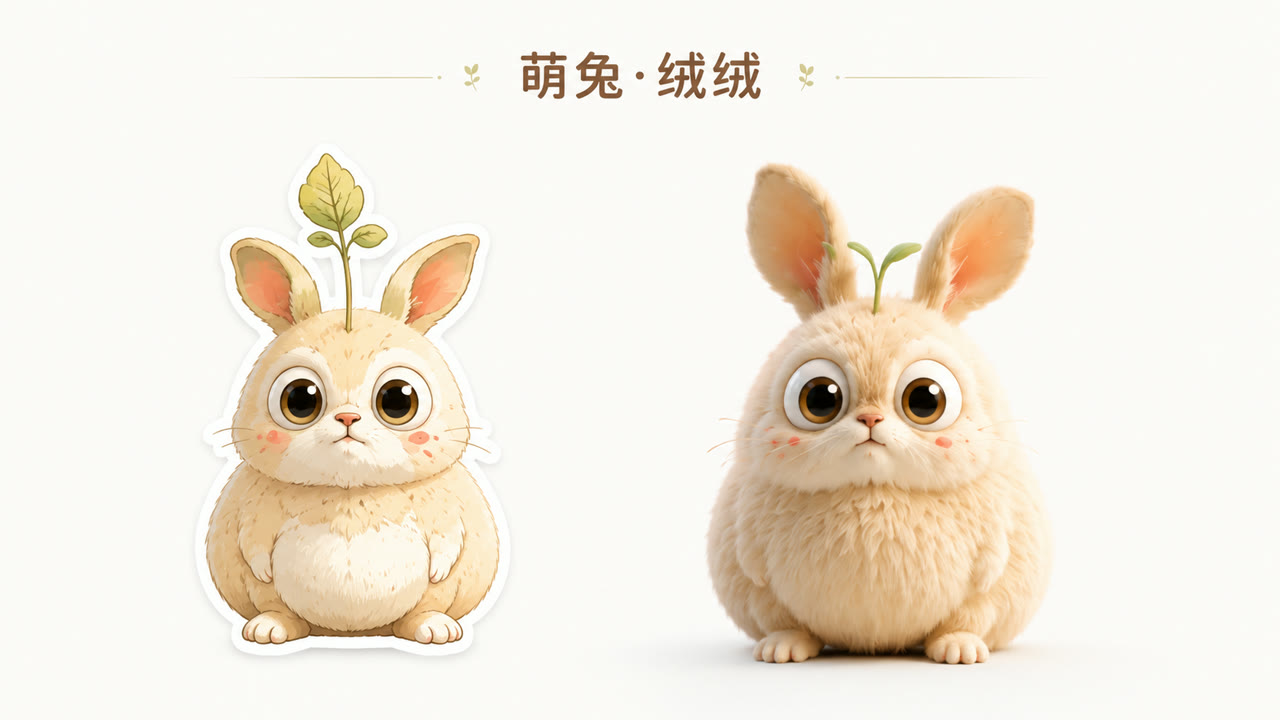
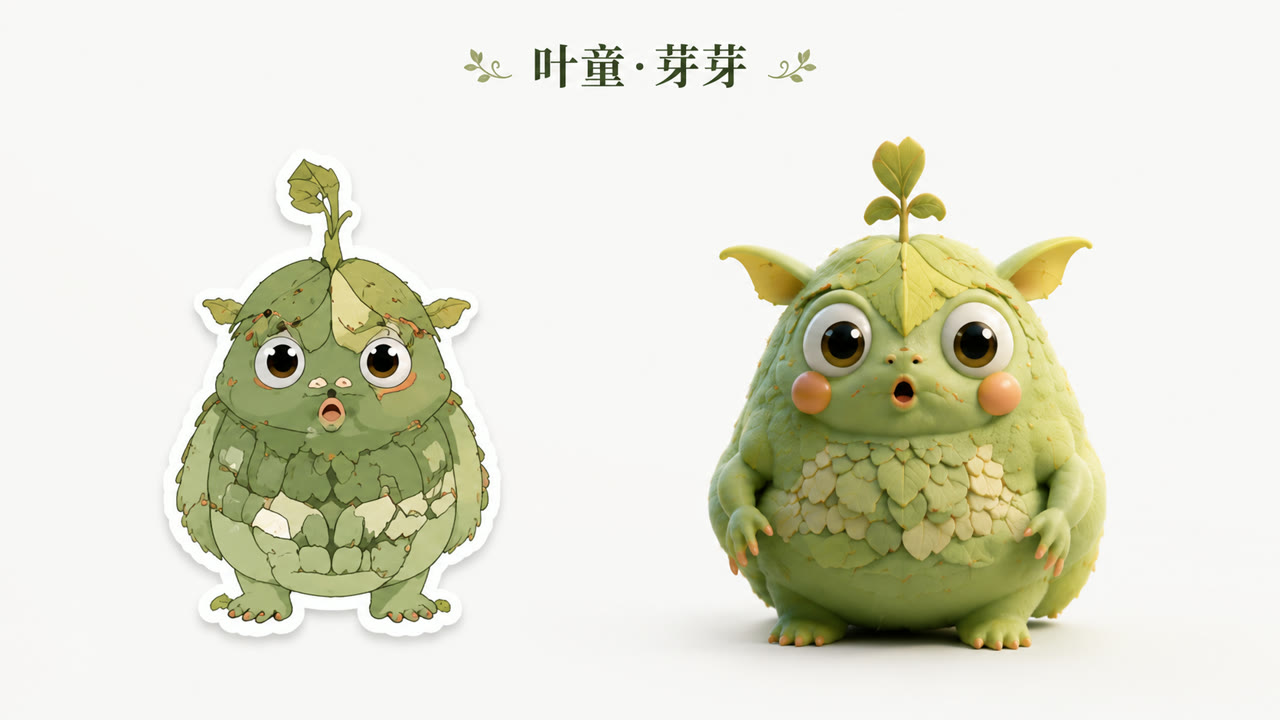
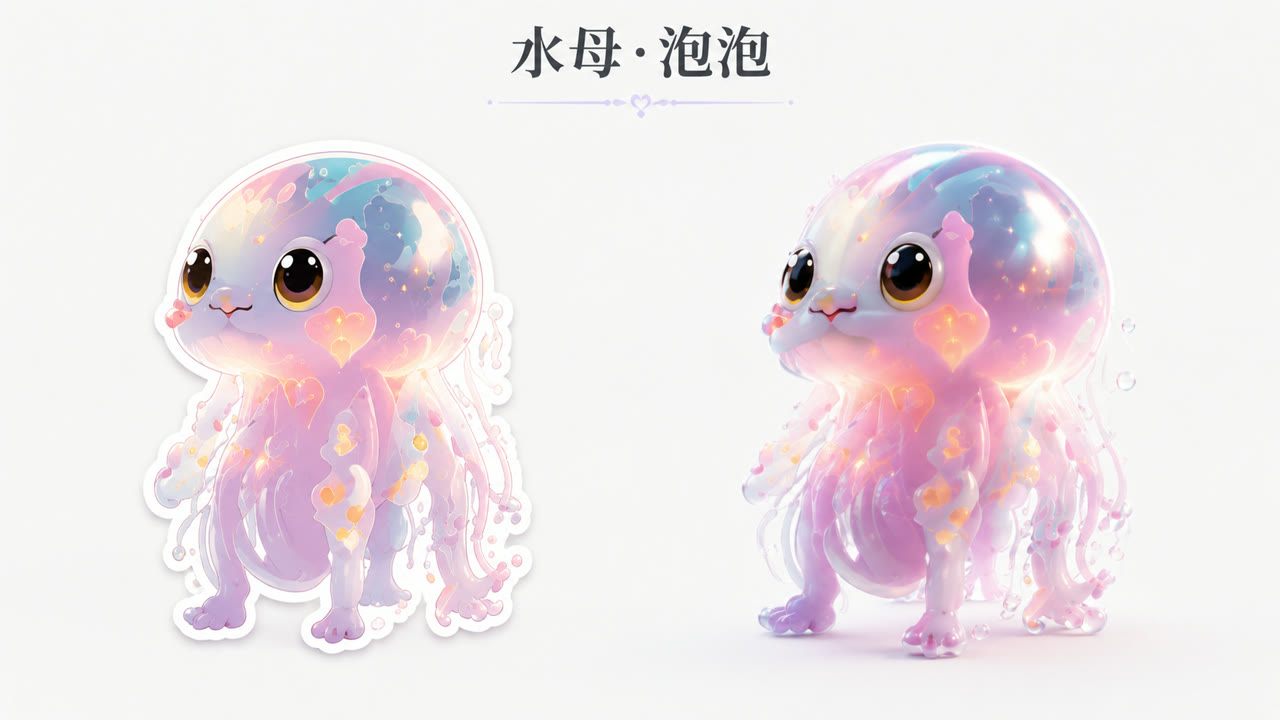
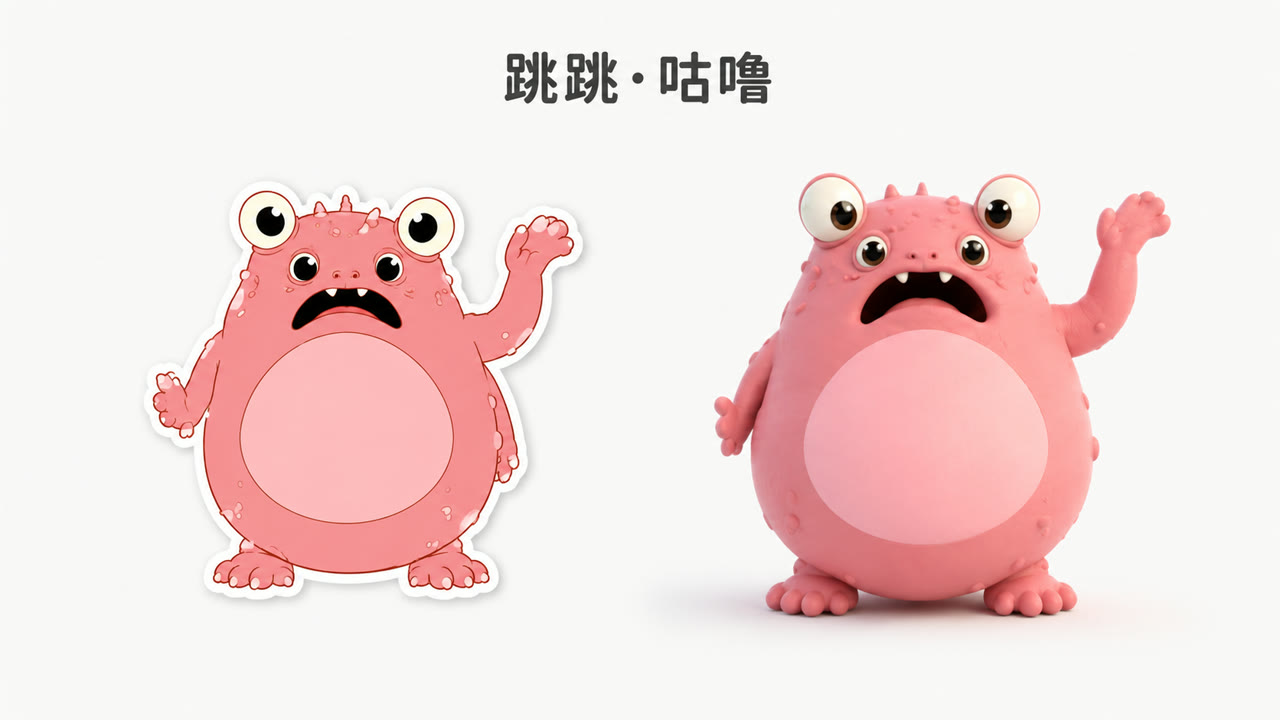
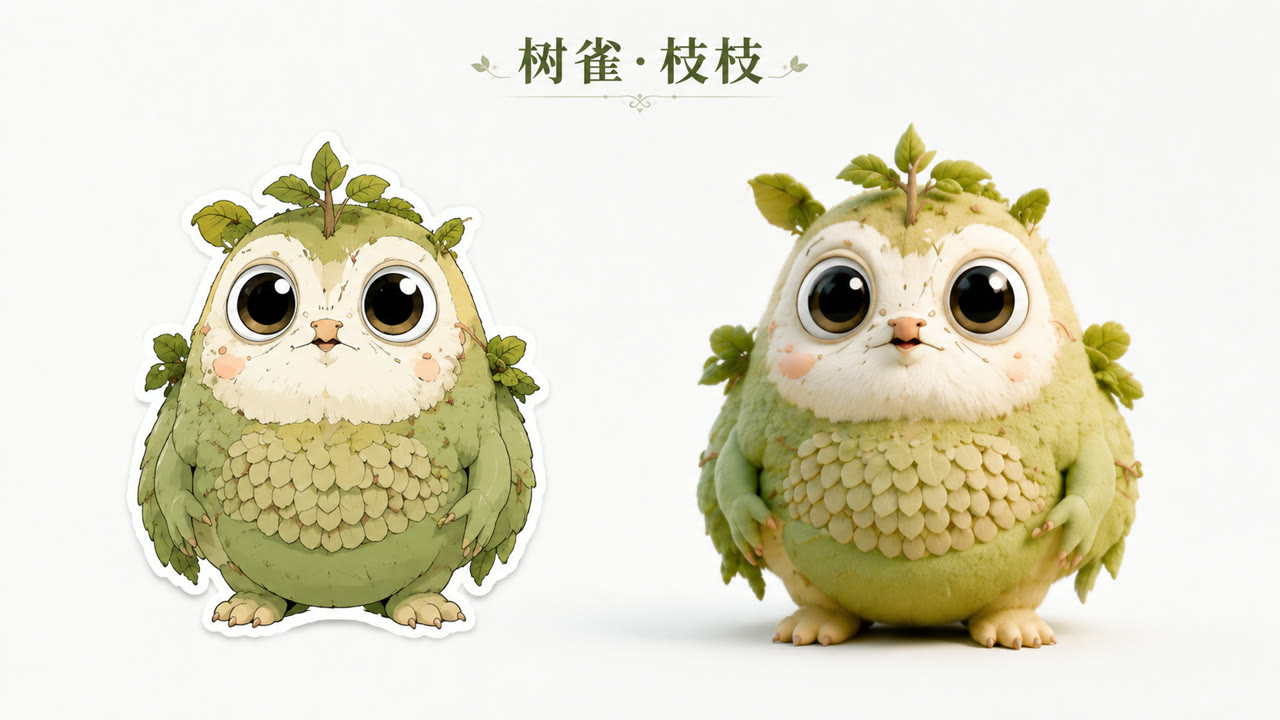
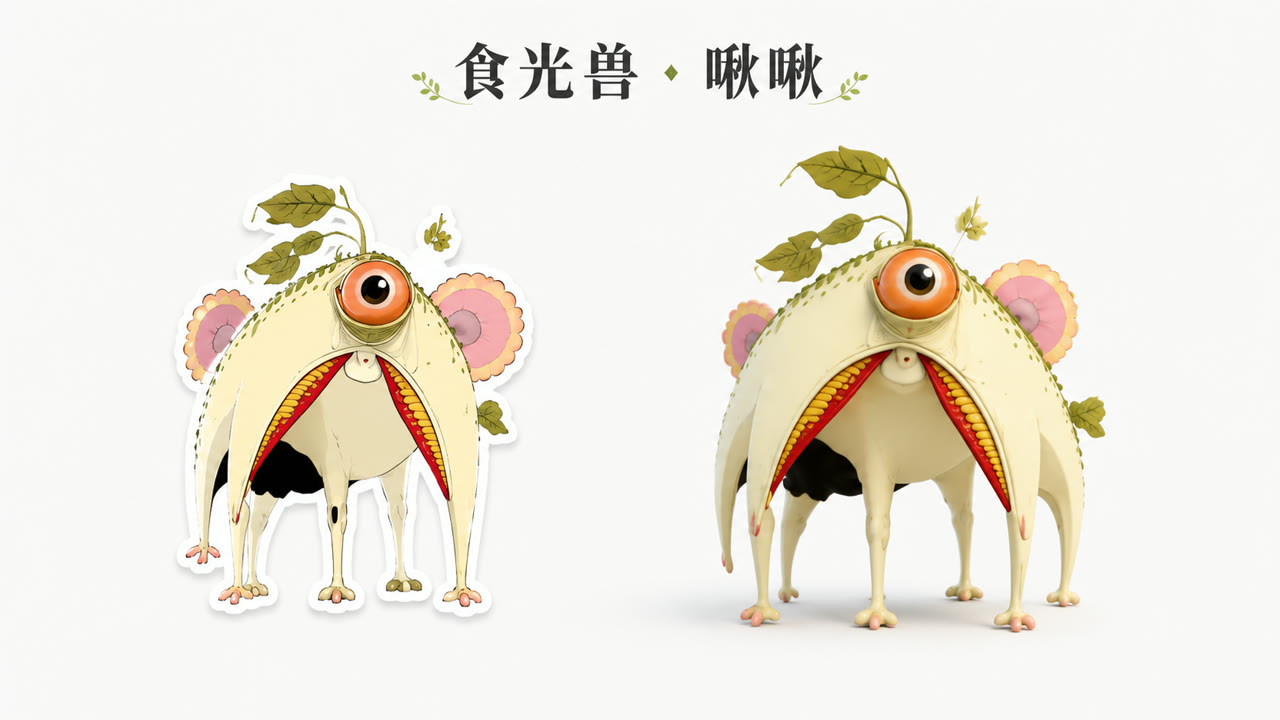
这条 30 秒的演示用了九张图片:一张给女子,一张给莲花秘境,七张给小生物,每种都有 2D 画稿和旁边的 3D 版本。她的脸从头到尾保持一致,而那些生物则从画稿里走进了 3D。在提示词里点名每个文件(Image 1、Image 2 等),让每个文件只负责一件事。
 Wan 3.0
装得下完整分镜表:10,000 个字符的提示词
Wan 2.5 把提示词限制在 1,500 个字符,大约刚够描述一个镜头。Yovid 上的 Wan 3.0 最多接受 10,000 个字符,所以整个计划都放得下:逐秒安排的镜头、每个镜头的运镜手法、配乐提示,以及每一句台词。
这条 30 秒的演示来自一条没有任何参考图的文字提示词。它排好了九个带时间码的镜头,从穿越云层的俯冲到缓缓拉远,Wan 3.0 按着顺序和节奏完成了。
 Wan 3.0
Yovid 上的 Wan 3.0 设置与积分
写提示词之前先选好画面比例,走位会按它来构图;从图片开始时,选“自适应”会沿用那张图片的比例。积分按输出秒数计费,只由分辨率决定,参考视频的秒数另外计入。
| 时长 | 2 到 30 秒默认 5 秒。Wan 2.5 只有 5 或 10 秒。 |
|---|---|
| 分辨率 | 480p、720p 或 1080p默认 720p;与 Wan 2.5 相同的三档。 |
| 画面比例 | 16:9、9:16、1:1、4:3、3:4 或自适应 |
| 输入方式 | 文字、首帧加可选的尾帧,或参考素材最多 10 张图片和 5 段 1–15 秒的视频(MP4 或 MOV,每个最大 100 MB)。 |
| 声音 | 默认开启,不额外收积分人声、音乐和音效;每次生成都可以单独关闭。 |
| 积分 | 每秒约 1.2、2.4 或 4.8分别对应 480p、720p 或 1080p,积分包标准价;一条 5 秒 720p 视频约 12 积分。 |
谁适合从 Wan 2.5 换到 Wan 3.0
大多数在找 Wan 2.5 的人,想要的是会说话、带配乐的视频,而不是把 10 秒的片段一段段拼起来。Wan 3.0 最擅长这些工作:
- 短剧与小品创作者:超过 10 秒的对白场景,再用参考图让同一批演员贯穿多集。
- 广告与社媒团队:一次生成就带旁白和音乐的产品广告,用你自己的照片让产品形象始终一致。
- 音乐与舞蹈视频创作者:歌词、节拍和口型同步都出自同一次生成的表演。
- 动画师与游戏工作室:风格化的片头和预告片,从水墨水彩到赛璐珞风格的 CG,一次 30 秒搞定。
- 手握 Wan 2.5 提示词库的团队:旧提示词是现成的起点:先原样跑一遍,再补上带时间码的节拍、参考素材和台词,把多出来的时长填满。
Wan 2.5 的继任模型 Wan 3.0 vs Seedance 2.5、MiniMax H3 和 Kling 3.0
表格里没有 Wan 2.5,因为 Yovid 不提供它。除最后一行外,每一格都直接读取各模型目前在 Yovid 生成器里提供的设置。
| 功能 / 模型 | Wan 3.0 |  Seedance 2.5 |  MiniMax H3 |  Kling 3.0 |
|---|---|---|---|---|
| 最长时长 | 30 秒 | 30 秒 | 15 秒 | 15 秒 |
| 最高分辨率 | 1080p | 1080p | 2K | 1080p |
| 画面比例 | 16:9, 9:16, 1:1, 4:3, 3:4 | 16:9, 9:16, 1:1, 4:3, 3:4, 21:9 | 21:9, 16:9, 4:3, 1:1, 3:4, 9:16 | 16:9, 9:16, 1:1 |
| 参考图 | 10 | 30 | 9 | — |
| 参考视频 | 5 | 10 | 3 | — |
| 编辑或延长上传的视频 | — | 支持 | — | — |
| 5 秒 720p 所需积分 | 12 | 31 | 23 | 13 |
| 最适合 | Wan 2.5 那类带声音的视频,现在最长 30 秒,预算也不高。 | 大量参考素材组合,以及编辑或延长上传的视频。 | 最长 15 秒的锐利 2K 视频。 | 最高 1080p、生动的 15 秒角色视频。 |
积分为积分包标准价下生成 5 秒 720p 视频的消耗(模型没有 720p 时取最接近的分辨率),随 Yovid 实时价格更新。
Wan 3.0 作为 Wan 2.5 的替代:优势与局限
换到 Yovid 上的 Wan 3.0,你能得到什么,又要放弃什么。
优势
- 三倍时长:每条视频 2 到 30 秒,Wan 2.5 只有 5 或 10 秒。
- 声音不另外收费:人声、音乐和音效默认开启,价格与无声视频相同。
- Wan 2.5 没有的参考素材:最多 10 张图片和 5 段视频,让人物、产品和场景保持一致。
- 更长的提示词:最多 10,000 个字符,Wan 2.5 只有 1,500,所以带时间码的分镜表也放得下。
局限
- 不是 Wan 2.5 本身:如果项目必须与已用 Wan 2.5 做好的素材相匹配,Yovid 无法复现那个模型;Alibaba Cloud Model Studio 仍保留着 2.5 预览版的文档。
- 不能上传音频:Wan 2.5 的 API 可以围绕你自己的音频文件生成视频;在 Yovid 上,Wan 3.0 使用的是文字、图片和视频。
- 套餐权限:免费版不可用。Lite 及以上套餐或任意一次性积分包可解锁 Wan 3.0,包括 1080p。
- 分辨率:和 Wan 2.5 一样,最高仍是 1080p。需要 2K 或 4K,可以选 MiniMax H3 或 Veo 3.1,或用 Yovid 的 AI 视频超分放大处理成片。
如何在 Wan 3.0 上运行 Wan 2.5 风格的提示词
- 第 1 步
打开 Wan 3.0
从本页进入,生成器会默认选好 Wan 3.0。模型列表里没有 Wan 2.5。
- 第 2 步
写下场景和声音
描述镜头,把对白放进引号并注明语言,有的话再添加首帧,或最多 10 张图片和 5 段视频。
- 第 3 步
设置时长并生成
选择 2 到 30 秒、比例和分辨率,确认积分消耗,然后生成并下载 MP4。
Wan 3.0 提示词示例,拿来就能改
Alibaba Wan 3.0 演示片里的真实提示词(有删减,并由中文翻译而来),旁边就是它们生成的视频。每一条都会在 Yovid 的生成器里以 Wan 3.0 打开;提到 Image 1、Image 2 等的提示词,需要附上你自己的参考图。
谢幕,一镜到底
文生视频 · 24 秒A 24-second, 16:9 single continuous take with a realistic film look, one 35 mm lens and no cuts. A singer of about 28, dark hair pinned up, in a muted wine-red velvet gown, has nearly missed her entrance. 0–12 s: the camera backs away fast as she threads a narrow backstage, past a makeup artist blotting her forehead, a rolling costume rack and a painted flat pushed across her path; the stage manager says into his headset, "布景就位,灯光准备,主幕待命。" (Set in place, lights ready, main curtain on standby.) 12–21 s: in the wings he raises a hand: "最后八小节。" (Last eight bars.) The orchestra thins to bass and sparse piano, and the camera slowly circles her as she closes her eyes. 21–24 s: "Three… Two… One!" The cue light turns green, the curtain rises and she steps into the light before a full house.
来源:Alibaba Cloud Model Studio · Wan 3.0
试试这条提示词八种语言,同一段副歌
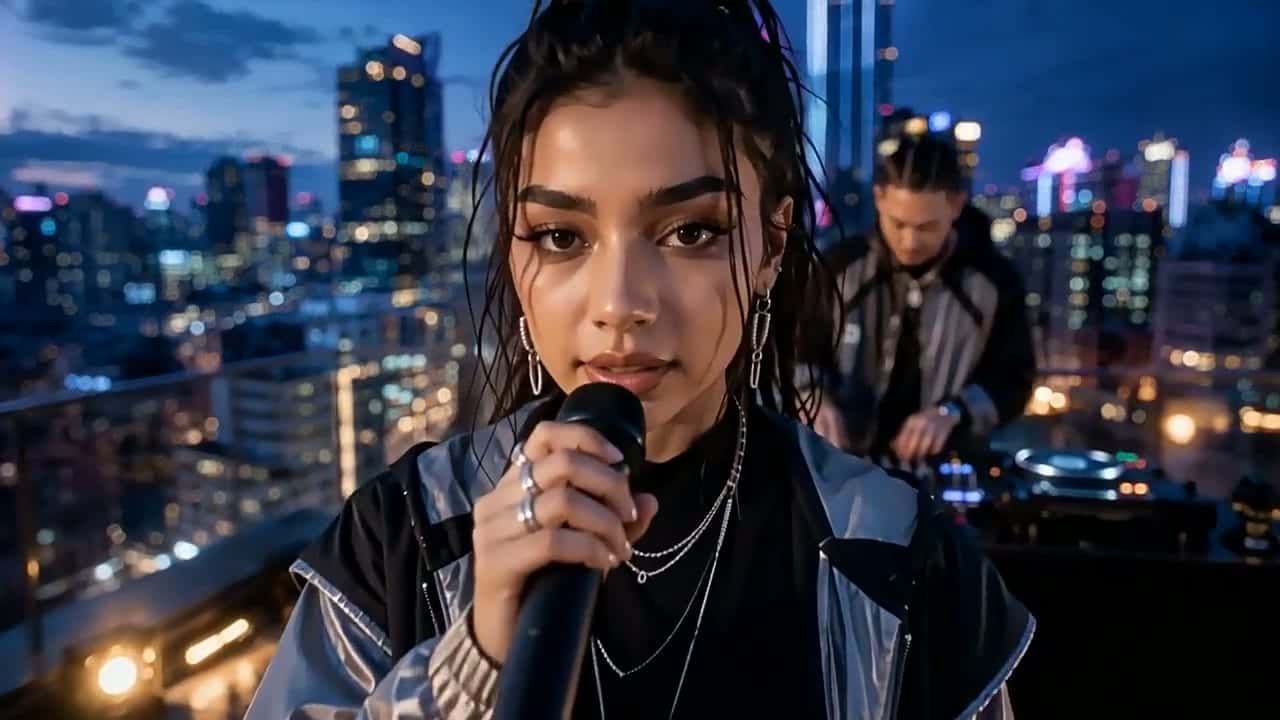
3 张参考图 · 24 秒A 24-second photoreal hip-hop video on a city rooftop at blue hour. Image 1 sets the four-piece crew (female lead vocalist, male DJ, two hype performers), Image 2 the lead’s face and silver-black techwear, Image 3 the rooftop stage and skyline. An original 106 BPM anthem with a two-bar synth-and-brass hook. Eight shots, one language each, every line on the beat: "One beat." "同一个节拍。" "ひとつのリズム。" "하나의 리듬." "Um só ritmo." "จังหวะเดียวกัน." "Un mismo ritmo." "إيقاع واحد." At the 21-second drop the camera pulls back to the whole crew: "Different voices, one beat." Exact lip sync, the same face and voice throughout, no captions or logos.
来源:Alibaba Cloud Model Studio · Wan 3.0
试试这条提示词猫与狼切磋
2 张参考图 · 30 秒A 30-second, 16:9, 1080P cinematic 3D animated action short. @Image 1 is the only tabby-cat heroine: brown-grey stripes, amber eyes, teal hooded cape, bronze shoulder guards, ringed tail. @Image 2 is the only grey-wolf hero: layered grey fur, ice-blue eyes, blue-and-gold cloud-pattern robe. Their swords stay sheathed on their backs throughout. In a ruined cave temple under a giant weathered stone Buddha head they spar bare-handed: punches, sweeps and wrist grabs, a chase up broken stairs, a one-second slow-motion clash at the top of a leap, a ledge that gives way until he catches her wrist, and a back-to-back landing in drifting pink petals. No dialogue or music, only impacts, cloth, falling stone, footsteps and wind.
来源:Alibaba Cloud Model Studio · Wan 3.0
试试这条提示词走进莲花秘境
9 张参考图 · 30 秒A 30-second, 16:9 cinematic surreal Eastern fantasy. Image 1 is the only identity reference for a young woman with long, softly wavy dark-brown hair, an open light-blue denim shirt and cream trousers; keep her face identical in every shot. Image 2 fixes a hidden realm of giant translucent lotus flowers glowing peach, coral and pale gold. Images 3–9 each show one small creature, 2D on the left and 3D on the right. She parts the vines and walks in; she touches a lotus and a glowing drop reflects three of the 2D creatures; they leap a stream and turn into their 3D forms; she kneels, smiling, as they gather around her; the camera rises as every lotus blooms at once. Live action blended with film-grade CG, no captions or logos.
来源:Alibaba Cloud Model Studio · Wan 3.0
试试这条提示词
Yovid 上的更多视频模型
从 Wan 2.5 换到 Wan 3.0 的进阶指南
对比 Yovid 上的所有视频模型,再学会写出能用足 Wan 3.0 额外时长的带时间码长提示词。